

AI
Edit-Ready Training: What 2,663 Runs Reveal About LLM Weight-Space Editing
Can an LLM agent directly rewrite a vision classifier's weights without gradients? A November 20, 2026 Ulm University benchmark (2,663 edit runs, 76,632 tool calls) shows Edit-Ready Training lifts GPT-6 Astra and Claude Opus 5.5 by up to +0.44—while open-weight editors lag.
8 min read
Edit-Ready Training: What 2,663 Runs Reveal About LLM Weight-Space Editing
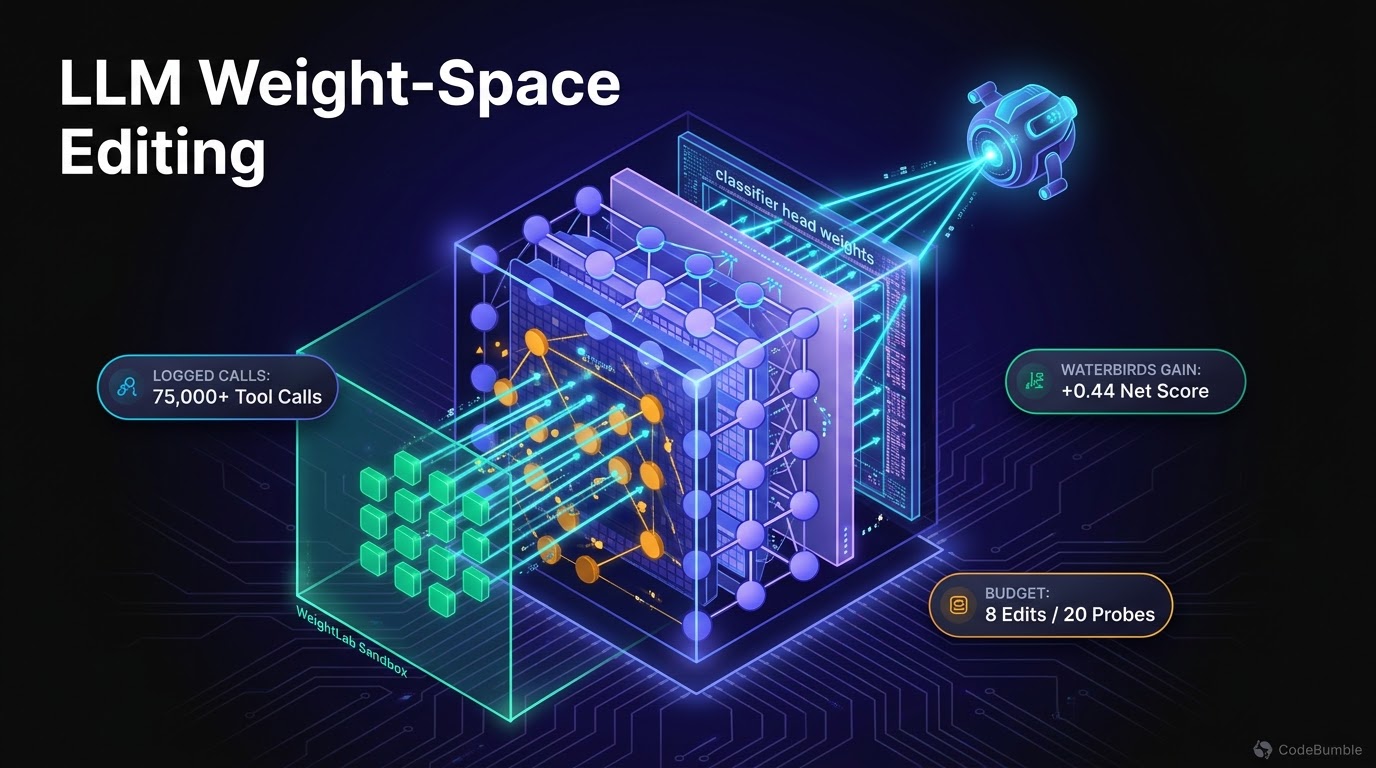
Updating a deployed image classifier for a single misclassified subgroup or confused class pair normally means collecting new labels and running gradient fine-tuning—risking collateral drift across unrelated classes. On November 19–20, 2026, Ulm University researchers Timo Ropinski and Sebastian Kranz published arXiv:2611.26408v1, the first systematic benchmark of LLM-driven weight-space programming on vision models, logging 2,663 edit processes and 76,632 tool calls across five LLMs (GPT-6 Astra, Claude Opus 5.5, DeepSeek-V4.1-Flash, GLM-5.3-Flash, and Gemma-4-26B) alongside Edit-Ready Training (ERT).
Executive Summary
- What Shipped: The WeightLab tool-use benchmark (
16gradient-free inspection and weight-editing tools) and Edit-Ready Training (ERT), a training-time rehearsal method that prepares ResNet-18, ResNet-50, and ViT-B/16 classifiers for direct LLM weight edits (arXiv:2611.26408v1). - Headline Gains on Hard Tasks: On standard (ERM) networks where LLMs struggle, ERT raised net edit scores (
success - side effect) on Entity-30 confusion fixes from0.46to0.79for GPT-6 Astra and0.44to0.74for Claude Opus 5.5, and on Waterbirds ViT-B/16 from0.50to0.74(Astra) and0.33to0.76(+0.44,p = 0.008, Opus) (arXiv:2611.26408v1). - Frontier vs. Open-Weight Split: Across nine settings, ERT achieved the highest mean net score for Astra (
0.74) and Opus (0.72), whereas three open-weight editors (DeepSeek-V4.1-Flash,GLM-5.3-Flash,Gemma-4-26B) showed no statistically significant paired gain from ERT (Emergent). - Key Caveat: Even after frontier LLM edits, full test-set accuracy still ends
3to4percentage points below the unedited baseline across all training methods (ERM,LS,ENN,ERT).
Architecture & How It Works
The Ulm University framework separates into two phases: Edit-Ready Training (ERT) at model training time, and Iterative Weight-Space Programming (WSP) at inference time inside the WeightLab MCP-style tool sandbox.
How Edit-Ready Training (ERT) Shapes Features
Standard cross-entropy training (ERM) optimizes classification accuracy without encouraging concepts to sit in isolated, easily editable feature units. In a pre-study, the authors observed that Claude Opus 5.5 modified only the classifier head in >90% of edits, typically writing a sparse, rank-one update along the feature contrast between support images (S) and reference images (R).
ERT rehearses those exact closed-form head edits during every training step without keeping any temporary edit:
- Compute Contrast: For an episode's support images
Sand reference imagesR, compute mean backbone featuresmu_Sandmu_R, then derive a contrast directiondusing either Top-8 units (16numbers across source classyand target classt) or Feature direction (a normalized rank-one projection). - Simulate Closed-Form Head Edit: Construct a temporary head
W' = W_0 + beta * (e_t - e_y) * d^T, wherebetais clipped to[0, 10]to flip support logits by margindelta = 1. - Backpropagate Post-Edit Loss: Evaluate cross-entropy on unseen query images
Q(did the edit generalize?) plus KL divergence on reference imagesR(did unrelated predictions stay intact?), and backpropagate gradients throughW'into the entire backbone.
flowchart LR
    A[Training Batch + Support/Reference Episodes] --> B[Backbone Features mu_S - mu_R]
    B --> C[Closed-Form Head Edit Simulation W']
    C --> D[Query Loss CE + Reference Loss KL]
    D --> E[Backprop into Backbone & Discard W']
    E --> F[Trained Classifier]
    F --> G[WeightLab Sandbox: 20 Probes / 30 Reads / 8 Edits]
    G --> H[LLM Agent: Inspect -> Edit -> Submit]
WeightLab Sandbox Protocol & Tool Budget
Inside WeightLab, blinded LLM agents never see raw images or gradient descent. They receive an anonymous task_id, 5 support images (relabeling) or 8 support images (confusion/subgroup fixes), and 64 reference images, enforced under strict call budgets (arXiv:2611.26408v1, Appendix A):
| Budget Category | Hard Limit | Included WeightLab Tools |
|---|---|---|
| Free Calls | Unlimited (max 150 turns) |
open_task, budget_status, undo_last_edit, reset_to_original, submit |
| Forward Probes | 20 calls |
probe_predictions, probe_activations, probe_logit_contributions |
| Weight Reads | 30 calls (max 512 values/read) |
list_parameters, list_layers, read_weights |
| Weight Edits | 8 calls (max 65,536 params/edit) |
set_weights, add_to_weights, scale_weights, scale_input_channels, edit_entries |
Here is the minimal tool-loop contract an agent follows inside WeightLab:
{
  "protocol": "weightlab-v1",
  "budgets": { "probes": 20, "reads": 30, "edits": 8, "max_edit_params": 65536 },
  "workflow": [
    "open_task(task_id)",
    "probe_logit_contributions(layer='fc')",
    "add_to_weights(tensor='fc.weight', rows=[target, source], values='...')",
    "probe_predictions(split='support_and_reference')",
    "submit()"
  ]
}
Benchmarks, Cost & Latency Analysis
Main Results: ERT vs. ERM, Label Smoothing & ENN
The benchmark spans nine (task, dataset, backbone) settings across Waterbirds (ResNet-18, ViT-B/16), CIFAR-100 (ResNet-18, ViT-B/16), Entity-30 (ResNet-50), and PACS (ResNet-18, ViT-B/16). Net score is success - side effect on held-out test images (arXiv:2611.26408v1, Table 1):
| Setting | Editor | ERM (Std) | Label Smoothing | ENN (Gradient) | ERT (Ours) |
|---|---|---|---|---|---|
Waterbirds Relabel (R18) |
GPT-6 Astra | 0.40 |
0.42 |
0.47 |
0.63 (+0.23) |
Waterbirds Relabel (ViT-B/16) |
GPT-6 Astra | 0.50 |
0.57 |
0.74 |
0.74 (+0.24) |
Entity-30 Confusion (R50) |
GPT-6 Astra | 0.46 |
0.53 |
0.81 |
0.79 (+0.33) |
| Mean Across All 9 Settings | GPT-6 Astra | 0.63 |
0.63 |
0.71 |
0.74 (+0.12) |
Waterbirds Relabel (R18) |
Claude Opus 5.5 | 0.41 |
0.48 |
0.52 |
0.63 (+0.16) |
Waterbirds Relabel (ViT-B/16) |
Claude Opus 5.5 | 0.33 |
0.62 |
0.79 |
0.76 (+0.44) |
Entity-30 Confusion (R50) |
Claude Opus 5.5 | 0.44 |
0.51 |
0.60 |
0.74 (+0.30) |
| Mean Across All 9 Settings | Claude Opus 5.5 | 0.60 |
0.65 |
0.68 |
0.72 (+0.12) |
Open-Weight Editors & Compute/Latency Telemetry
In Appendix E and Appendix H, the researchers evaluated three open-weight models across eight settings (excluding Entity-30) and logged total compute and editing latency across 2,663 edit processes (76,632 tool calls, 234.5 total editing hours) as of November 18, 2026 (arXiv:2611.26408v1, Table 15):
| Editor Model | Edit Processes | Tool Calls | Median Changed Weights | Median Time / Edit | 8-Setting Mean (ERM -> ERT) |
|---|---|---|---|---|---|
GPT-6 Astra (high) |
401 |
11,782 |
252 |
3.1 min |
0.63 -> 0.74 (9-setting) |
Claude Opus 5.5 (default) |
1,098 |
25,354 |
27 |
2.7 min |
0.60 -> 0.72 (9-setting) |
| DeepSeek-V4.1-Flash | 315 |
10,831 |
44 |
17.1 min |
0.67 -> 0.70 (p = 0.44) |
| GLM-5.3-Flash | 401 |
14,027 |
24 |
2.7 min |
0.50 -> 0.49 (p = 0.90) |
Gemma-4-26B (thinking) |
448 |
14,638 |
10 |
0.7 min |
0.31 -> 0.37 (p = 0.30) |
Benchmark Caveats & Saturation:
- Easy Settings Already Saturate: On CIFAR-100 relabeling and PACS subgroup fixes, standard
ERMnetworks already scored0.64–0.82for Astra and0.68–0.81for Opus, leaving near-zero headroom (-0.02to+0.03) for dedicated preparation. - Open-Weight Divergence: While
DeepSeek-V4.1-Flashapproached frontier net scores (0.70), it took17.1minutes per edit (6xslower than Opus's2.7min), andGLM-5.3-FlashandGemma-4-26Bfailed to recover the accuracy lost on early edits—ending4–12and10–18points below baseline accuracy, respectively. - Training Cost: Preparing
~1,300networks (including ablations and tuning) required385GPU-hours across RTX PRO 6000 Blackwell (320hrs) and H100/A100 (65hrs) GPUs, while the three open-weight editors consumed~750 millionprompt tokens.
Production Deployment & Trade-Offs
When to Use Weight-Space Programming vs. Fine-Tuning
- Test Standard
ERMFirst: Because ERT's gain correlates negatively with the unedited network's editability (r = -0.83for Astra,-0.82for Opus), run a quick 5-edit pilot on your existing classifier before retraining. If your standard model already scores>= 0.70, ERT adds minimal value. - Use
ERTfor Hard Spurious Correlations or Class Confusions: When models tangle concepts in the backbone (like Waterbirds background bias or fine-grained Entity-30 confusions), ERT reduces the required head weight norm by ~5x (l2norm1.4vs.7.5on Waterbirds ResNet-18) so a frontier agent can isolate the fix in5–6edit calls without touching the backbone. - Budget
8Edits, Not12—and Expect a3–4Point Accuracy Tax: Edit-budget ablations (1, 4, 8, 12calls) showed zero significant improvement beyond8edits (Opus used a median of5–6calls). However, because every method still loses3–4percentage points of overall test accuracy after final submission, do not replace gradient fine-tuning in safety-critical production pipelines where zero regression on global accuracy is mandatory.
Gotchas & Limitations
- Model Scale & Task Scope: Results currently cover image classifiers (
ResNet-18,ResNet-50,ViT-B/16), not object detectors, VLMs, or generative diffusion models. - Editor-Specific Sensitivity: Open-weight editors (
GLM-5.3-Flash,Gemma-4-26B) ranked trained networks differently from Opus (0.02and-0.14rank correlation) and left weights untouched in57/251(GLM) and135/251(Gemma) runs—always validate prepared models with the exact LLM editor you plan to deploy.
Frequently Asked Questions
What is Edit-Ready Training (ERT)?
Edit-Ready Training (ERT), introduced in arXiv:2611.26408v1 on November 19–20, 2026, is a training-time objective that simulates closed-form classifier head edits (Top-8 units and Feature direction) during backpropagation so trained vision models organize concepts into cleanly editable feature directions.
How does WeightLab prevent LLMs from cheating with gradient descent?
WeightLab exposes 16 gradient-free MCP-style tools under strict per-task budgets (20 forward probes, 30 weight reads capped at 512 values each, and 8 weight edits capped at 65,536 parameters each) while blocking raw image access and preventing the agent from adding layers or adapters.
How much does ERT improve GPT-6 Astra and Claude Opus 5.5 edits?
Across nine settings, ERT raised mean net scores (success - side effect) from 0.63 to 0.74 for GPT-6 Astra and 0.60 to 0.72 for Claude Opus 5.5, with the largest gains on hard tasks like Entity-30 confusion (0.46 -> 0.79 Astra; 0.44 -> 0.74 Opus) and Waterbirds ViT-B/16 (0.50 -> 0.74 Astra; 0.33 -> 0.76 Opus).
Do open-weight LLMs benefit from Edit-Ready Training?
Not reliably in this study. Across eight settings, DeepSeek-V4.1-Flash (+0.03, p = 0.44), GLM-5.3-Flash (-0.01, p = 0.90), and Gemma-4-26B (+0.06, p = 0.30) showed no statistically significant paired gain from ERT over standard training.
Does LLM weight-space editing hurt overall model accuracy?
Yes. Even with frontier editors (GPT-6 Astra and Claude Opus 5.5) and ERT, overall test-set accuracy after the final edit still ends 3 to 4 percentage points below the unedited classifier across all tested training methods.
Sources
- arXiv:2611.26408v1: Training Vision Models for LLM-Driven Weight-Space Programming — Timo Ropinski & Sebastian Kranz (Ulm University), published November 19–20, 2026; verified November 22, 2026 (ERT formulation, WeightLab 16-tool protocol, 2,663 edit processes, 76,632 tool calls, and Tables 1–15).
- Emergent: Edit-Ready Training Lets LLMs Rewrite Vision Model Weights — Published November 20, 2026; verified November 22, 2026 (independent synthesis of frontier vs. open-weight editor divergence and 3–4 point accuracy trade-off).
- Cool Papers / arXiv:2611.26408 & Ulm Visual Computing Project Page — Indexed November 19–20, 2026; verified November 22, 2026 (paper metadata and benchmark/trajectory release scope).