

AI
Hugging Face Custom CDN: Why Open-Model Traffic Outgrew Commodity CDNs at 1 Exabyte/Month
On November 20, 2026, Hugging Face disclosed that it now ships nearly 1 exabyte of open models and datasets monthly via a custom CDN hitting 420 GB/s peaks. Here is why commodity web CDNs broke at AI checkpoint scale—and what platform teams should copy.
8 min read
Hugging Face Custom CDN: Why Open-Model Traffic Outgrew Commodity CDNs at 1 Exabyte/Month
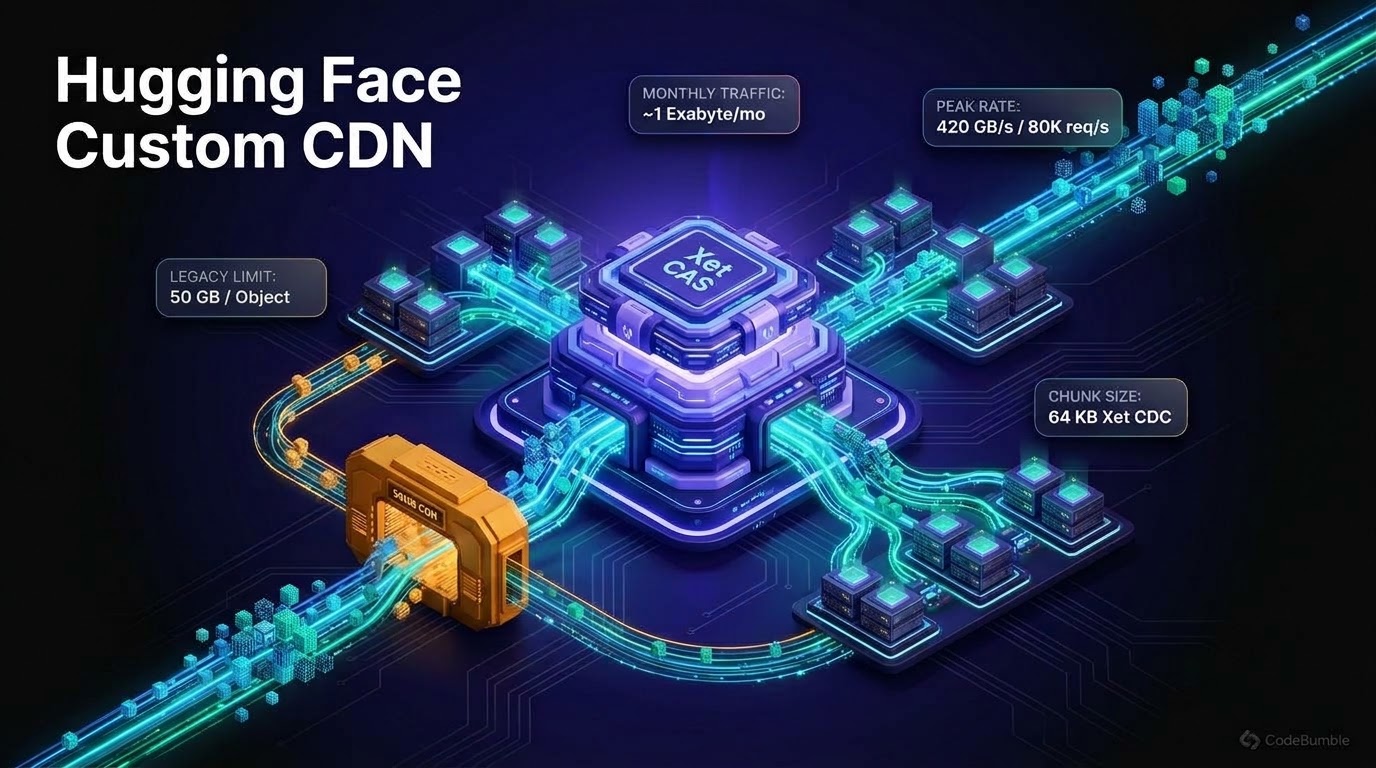
Standard web content delivery networks were engineered to cache small HTML, CSS, and image fragments for millions of human browsers—not to stream 100+ GB Safetensors checkpoints at line rate to GPU clusters on model launch day. On November 20, 2026, Hugging Face co-founders Julien Chaumond and Thomas Wolf disclosed that the Hub now serves nearly 1 exabyte (~1,000 PB) of open models and datasets per month through a custom-built CDN, hitting company-reported peaks of 420 GB/s and 80,000 concurrent requests per second (explainx.ai; Emergent).
Executive Summary
- Traffic Scale: Hugging Face states it distributes nearly
1 exabyte/month(~31.7 PB/dayaverage) across500,000+models and100,000+datasets, with release-day spikes reaching420 GB/sand80,000 req/s(explainx.ai; Emergent). - Why Commodity CDNs Failed: As documented in Hugging Face's Rearchitecting Uploads and Downloads post, AWS CloudFront's
50 GBper-object limit forced131 GBmodels like Llama-3-70B into20 GBshards, while traditional edge caches optimize for small web assets rather than multi-gigabyte whole-checkpoint pulls. - Xet + CAS Storage Backbone: The custom download path pairs with Hugging Face's Xet content-addressed storage (
~64 KBcontent-defined chunks grouped into~64 MBxorbs oncas-server.xethub.hf.co), which migrated30+ PBoff Git LFS (Xet on the Hub). - Verification Caveat: The
1 EB/month,420 GB/s, and80,000 req/sfigures are company-stated (no independent third-party bandwidth audit was attached), though Hugging Face published a live aggregate traffic map athuggingface-cdn-live.static.hf.space.
Architecture & How It Works
Hugging Face's November 20, 2026 disclosure is the download-side culmination of a two-year storage overhaul that replaced file-level Git LFS with chunk-level Xet content-addressed storage (CAS) and bespoke edge caching.
Why Commercial Web CDNs Misfire on AI Checkpoints
| Workload Dimension | Traditional Web CDN Assumption | Hugging Face AI Distribution Reality |
|---|---|---|
| Object Size | Many small assets (KB to low MB) | Few massive checkpoints (8 GB GGUF to 1 TB+ sharded models) |
| Client Topology | Human readers spread globally | Concentrated GPU clusters in select cloud regions |
| Cache Objective | High edge hit ratio across millions of users | Whole-object caching at line rate for synchronized cluster pulls |
| File-Size Ceiling | AWS CloudFront 50 GB object limit |
Multi-hundred-GB weights requiring 20 GB sharding workarounds |
flowchart LR
    A[Client: huggingface_hub / hf_xet] -->|1. Request File + Auth Token| B[Hugging Face Hub API]
    B -->|2. Reconstruction Metadata| C[Xet CAS: cas-server.xethub.hf.co]
    C -->|3. 64 KB CDC Chunks / 64 MB Xorbs| D[Custom AI CDN Edge Cache]
    D -->|4. Line-Rate HTTP / Range Reads up to 420 GB/s| E[GPU Inference & Training Clusters]
How Xet Chunking & Background Migration Work
In standard Git LFS, average Parquet and CSV files on the Hub range between 200–300 MB, average Safetensors files run around 1 GB, and quantized GGUF files frequently exceed 8 GB (From Files to Chunks). Because Git LFS tracks assets at the file level, modifying a single line of metadata in an 8 GB GGUF file or fine-tuning 5% of a 20 GB model forced a full-file re-upload, full-file re-download, and duplicate server-side storage across revisions.
Under Xet (hf_xet), files are split via content-defined chunking (CDC) into ~64 KB chunks and aggregated into immutable ~64 MB xorbs before transfer (Xet on the Hub). Identical tokenizer configs, base model layers, or unchanged Parquet row groups are physically stored once on cas-server.xethub.hf.co and deduplicated across repositories. When a non-Xet client pushes an LFS file, Hugging Face's background migration orchestrator batches up to 1,000 files or 500 MB per job via distributed queues to keep 500,000+ repositories synchronized without repository locks.
For developers and CI pipelines, pinning exact commit revisions in huggingface_hub prevents redundant pulls while leveraging Xet reconstruction:
from huggingface_hub import snapshot_download

local_dir = snapshot_download(
    repo_id="moonshotai/Kimi-K3.1-Pro",
    revision="main",  # Pin a 40-char commit SHA in CI to avoid drifting re-pulls
    allow_patterns=["*.safetensors", "*.json"],
)
Benchmarks, Cost & Latency Analysis
Traffic & Storage Telemetry
Because Hugging Face has not published an external audit of its 1 EB/month claim, engineers should separate November 20, 2026 company disclosures from earlier measured engineering benchmarks:
| Metric | Reported Value | Source & Confidence |
|---|---|---|
| Monthly Distribution Volume | ~1 Exabyte/month (~31.7 PB/day) |
Julien Chaumond, Nov 20, 2026 (company-stated; explainx.ai) |
| Peak Throughput & Concurrency | 420 GB/s / 80,000 req/s |
Thomas Wolf, Nov 20, 2026 (company-stated; explainx.ai) |
| Hub Repository Scale | 500,000+ models; 100,000+ datasets; 30+ PB migrated |
Emergent; From Files to Chunks |
| 24h Upload Baseline (Oct 2024) | 130.8 TB across 8.2M requests (88 countries) |
Rearchitecting Uploads & Downloads |
| Xet Deduplication Speedup | 2–3x faster transfers; 5 GB SQLite + 1 MB diff in 0.1 s vs. 13 min |
From Chunks to Blocks; Xet on the Hub |
Bandwidth Math & Release-Day Mega-Floods
Spreading 1 exabyte evenly across a 30-day month works out to roughly 31.7 PB/day, or an average sustained throughput of ~367 GB/s—yet real ML distribution is heavily skewed toward release-day spikes. When a frontier open-weight model lands on Hacker News or GitHub trending, thousands of automated CI runners, inference providers, and multi-node GPU clusters trigger synchronized full-checkpoint pulls and byte-range reads simultaneously, driving the 420 GB/s and 80,000 req/s peaks Wolf highlighted (explainx.ai). Hugging Face also exposed aggregate regional pull telemetry on its public live map (huggingface-cdn-live.static.hf.space) so SREs can observe cross-border model traffic patterns.
Egress Economics: Why Custom CDNs Are a Moat
At 1 exabyte/month, egress bandwidth—not disk storage—dominates unit economics. Commodity cloud egress and per-request CDN billing punish workloads where a single GPU cluster pulls 400 GB to 1 TB of weights simultaneously. Hugging Face subsidizes public model distribution as strategic platform spend (monetizing Team/Enterprise storage seats and governance features), whereas startups or sovereign AI hubs attempting to mirror frontier weights on flat SaaS pricing face severe margin compression unless they bill per terabyte transferred or peer directly near major GPU clouds (explainx.ai).
Production Deployment & Trade-Offs
Self-Hosted Mirror & Platform Checklist
For infrastructure teams running internal model registries or air-gapped GPU clusters, Hugging Face's architecture highlights five concrete design requirements (explainx.ai):
| Operational Area | Recommended Engineering Practice |
|---|---|
| Capacity Planning | Model peak checkpoint size (GB) multiplied by expected concurrent cluster pulls, not average daily traffic. |
| Cache Eviction Policy | Use whole-object caches sized for 20 GB shards rather than fragment-only LRU policies tuned for web pages. |
| Release Playbook | Stagger shard uploads and pre-warm us-east, eu-west, and ap-southeast mirrors before public announcements. |
| Supply-Chain Integrity | Enforce immutable commit SHAs, signed manifests, and mirrored SHA-256 checksums for fast rollback. |
| Cost Attribution | Track and price internal/external consumption per full terabyte pulled rather than per API request or seat. |
Enterprise Proxy & Air-Gapped Mirror Gotchas
- JFrog Artifactory Xet Limitation: In Hugging Face's enterprise Artifactory guide, engineering warned that Artifactory's Xet integration mimics the
/reconstructionsandxorbs/API surface while storing isolated per-file blobs underneath—eliminating global deduplication and roughly doubling storage footprint. Furthermore,hf_xetstill fetches chunk data directly fromcas-server.xethub.hf.coin standard Xet flows, which can hit Hub429rate limits if an enterprise remote shares one token; disabling Xet fallback lets Artifactory cache flat LFS files at half the storage cost unless you deploy a Hugging Face-native gateway. - Thundering Herd Protection on Cluster Restarts: Without a local pull-through mirror, autoscaling
100inference replicas after a spot-instance preemption can saturate a VPC NAT gateway or corporate WAN link. Pin immutable revisions and stage weights on regional NVMe or object storage (S3/GCS) inside the same availability zone as your GPUs. - Immutable Revisions & Security Scanning: Fast global distribution amplifies supply-chain mistakes. Always pin exact commit SHAs (never floating
main), verify SHA-256 manifests, and keep Hugging Face's automated Pickle/malware scanning checks intact rather than bypassing verification for speed.
When Commodity CDNs Still Fit
Do not over-engineer a custom CDN for small LoRA adapters (< 1–2 GB), tokenizer configs, or standard web assets. Commodity CDNs like CloudFront remain simpler and cheaper until your distribution profile shifts to synchronized multi-hundred-gigabyte checkpoint pulls into concentrated GPU regions.
Frequently Asked Questions
How much traffic does Hugging Face's custom CDN handle?
According to November 20, 2026 statements by co-founders Julien Chaumond and Thomas Wolf, Hugging Face serves nearly 1 exabyte (~1,000 PB) per month (~31.7 PB/day), with peaks of 420 GB/s and 80,000 requests per second (explainx.ai). These figures are company-stated without a published third-party audit.
Why did Hugging Face replace AWS CloudFront for model downloads?
In its Rearchitecting Uploads and Downloads engineering post, Hugging Face noted that CloudFront's 50 GB file-size limit and web-oriented caching assumptions conflicted with massive AI checkpoints (such as 131 GB Llama-3-70B models) and synchronized GPU cluster downloads.
Do developers need a new CLI flag to use the Hugging Face custom CDN?
No. The custom CDN and Xet CAS routing operate transparently behind huggingface_hub and hf_xet downloads without requiring manual CLI flag changes.
How does Xet storage relate to Hugging Face's custom CDN?
Xet replaces file-level Git LFS with content-defined chunking (~64 KB chunks packed into ~64 MB xorbs) on cas-server.xethub.hf.co, eliminating redundant transfers when only part of a model or Parquet dataset changes, while the custom CDN optimizes the high-throughput download path to GPU clusters.
Why can enterprise proxies like JFrog Artifactory miss Xet's deduplication benefits?
Per Hugging Face's Artifactory guide, Artifactory's Xet implementation stores isolated per-file blobs rather than globally deduplicated chunks, forfeiting cross-model chunk reuse and roughly doubling storage usage unless you fall back to flat LFS caching or deploy a Hugging Face-native gateway.
Sources
- explainx.ai: Hugging Face Custom CDN: 1 Exabyte Monthly Open-Model Traffic — Published November 20, 2026; verified November 22, 2026 (
~1 EB/month,420 GB/s,80,000 req/sdisclosures from Julien Chaumond and Thomas Wolf, bandwidth math, and self-hosting checklist). - Emergent: Hugging Face Moves Nearly 1 Exabyte Monthly via Custom CDN — Published November 21, 2026; verified November 22, 2026 (
500,000+models,100,000+datasets, and checkpoint scale context). - Hugging Face Engineering: Rearchitecting Hugging Face Uploads and Downloads — Published November 26, 2024; verified November 22, 2026 (CloudFront
50 GBobject limit,131 GBLlama-3-70B sharding, and CAS read/write architecture). - Hugging Face Engineering: Xet is on the Hub & Migrating the Hub from Git LFS to Xet — Published March 18 & July 15, 2025; verified November 22, 2026 (
64 KBCDC chunks,64 MBxorbs,500,000repos migrated). - Hugging Face Engineering: Hugging Face on JFrog Artifactory — Published May 8, 2026; verified November 22, 2026 (
cas-server.xethub.hf.cotoken flow and enterprise proxy deduplication caveats).